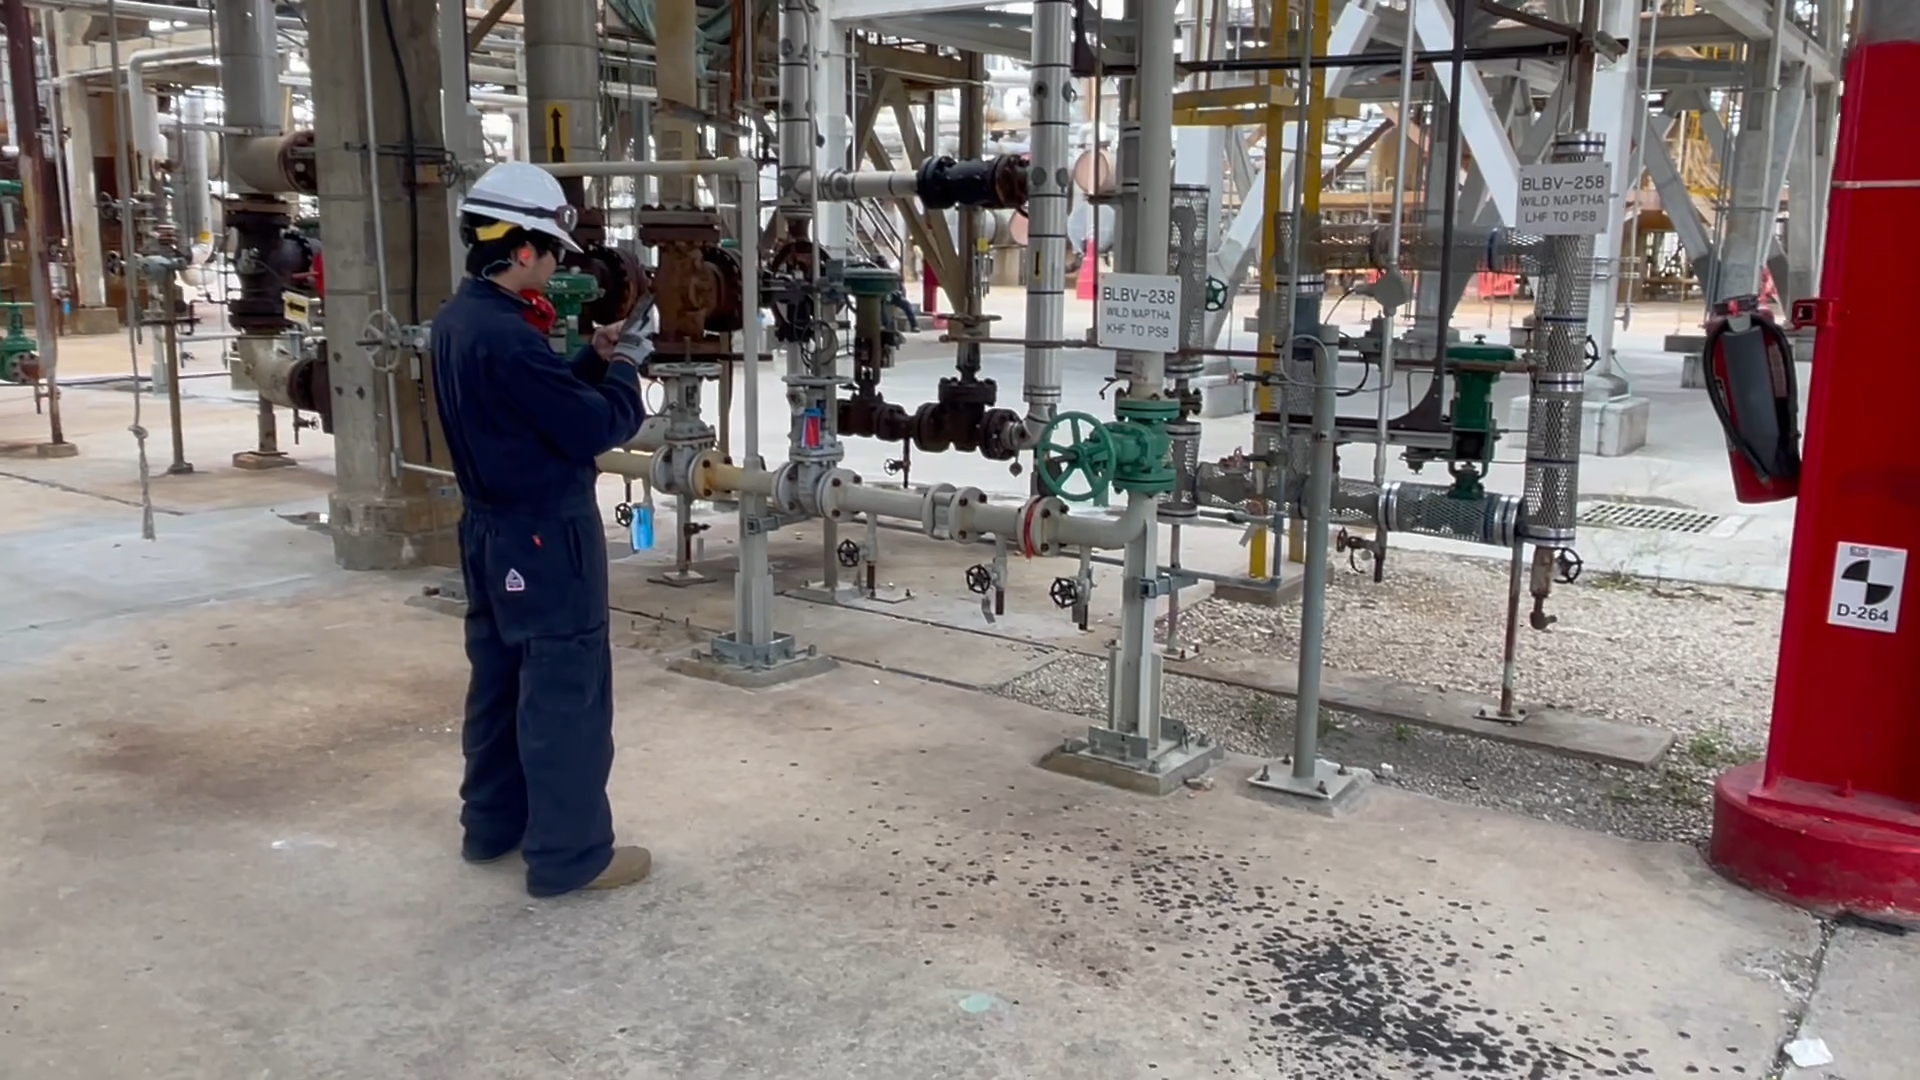
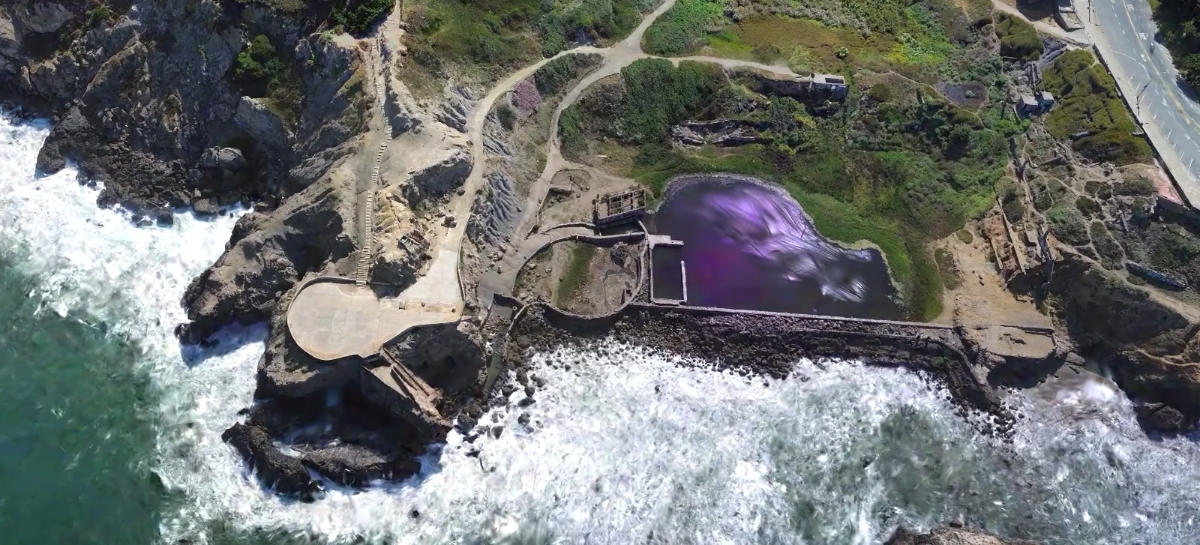
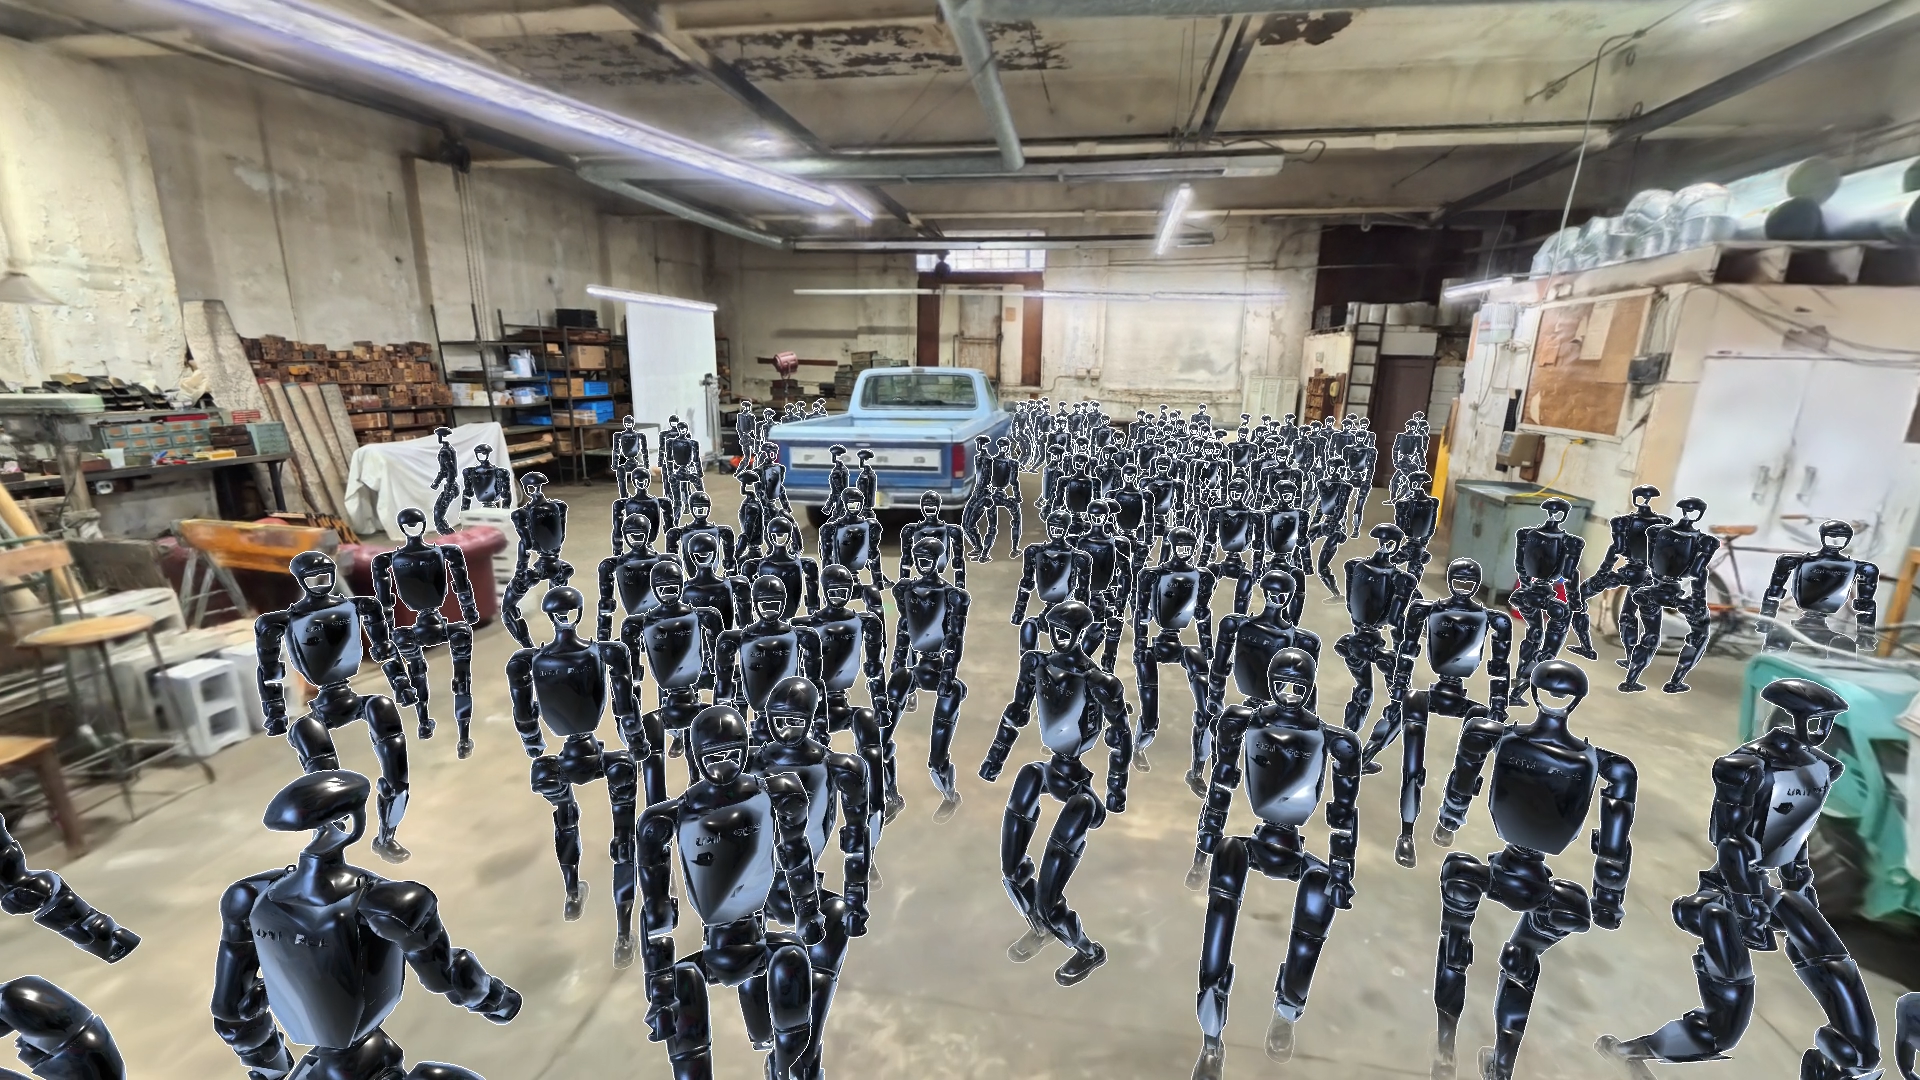
Query the world, track changes, and predict what's next.
We’re building a semantic layer that turns 3D reconstructions into spatial knowledge so people and machines can understand what’s there, how objects relate, and what actions are possible.
One spatial data layer that connects what a place looks like with what it contains, how it works, and how it changes.
From 3D geometry to real-world understanding
-
Spatially grounded semanticsEach point carries a descriptor for geometry, material and context. Understand objects, materials, and relationships in their real-world context, with insights tied to precise 3D locations and traceable to the underlying geometry and imagery.
-
Open-vocabulary understandingMove beyond predefined categories to query specific objects and concepts in natural language, and reason about their spatial relationships, not just recognize their presence.
-
Change over timeCompare captures to investigate what appeared, disappeared, or moved, grounding each change in its location and surrounding context so teams can understand more than a visual difference.
What spatial understanding makes possible
Industries we support
Related
Frequently Asked Questions
What does semantic understanding add to a 3D reconstruction?
Reconstruction captures a place’s geometry and appearance. Semantic understanding connects that geometry to objects, materials, and spatial relationships so people, AI agents, and machines can search and reason about a real place, rather than simply view it.
What kinds of questions can I ask?
Our research demonstrations show searches for specific objects and measurements within reconstructed spaces. The broader goal is to answer questions such as “What is blocking this entrance?” or “Can a robot pass through here?” with answers grounded in the site’s 3D geometry and location.
Is it limited to predefined object categories?
Our research uses open-vocabulary models rather than a fixed list of labels. This enables searches for specific objects and concepts expressed in natural language, with spatial context helping explain where things are and how they relate, not just which category they belong to.
Can it show what changed between captures?
Our change-detection research compares aligned 3D reconstructions of the same space to surface and describe differences between captures. Working demonstrations show how this approach can reveal what moved, appeared, or degraded. It compares captured states, rather than providing continuous live monitoring.
Is semantic understanding available today?
Semantic understanding is currently in research, with working demonstrations of object-level queries, site search, and change detection. Reconstruction and visual positioning are available today; semantic capabilities are being developed on that foundation. Contact our team to discuss your use case and the current capabilities.